AI dashboard and AI agents
Two screens — /ai, which shows what the AI has been doing across
your organisation, and /ai/agents, where you set a longer analysis
running and read what comes back.
The AI in Aegis reads and drafts. An agent run (one AI task you describe in a sentence and leave to work in the background) can draft a procedure, pull the obligations out of a long policy, or summarise where a framework stands. This chapter covers both screens: the AI Dashboard, a read-only health check, and the AI Agents page, where runs are started, watched and read.
An agent produces text and stops. It never writes into a policy, a risk or a control on its own. When a run finishes you read the result and choose what to do with it — copy it, save it as a record, or turn it into an action item. Each is a button a person presses.
Who uses it
Both pages need at least the Contributor role. A
Viewer who opens
/ai or /ai/agents is redirected to the "not
authorised" page. A
Contributor and a
Manager can read the dashboard,
start runs and act on results; an
Admin can also manage the AI models
in settings, where that feature is switched on for your organisation. Cancelling
a run needs the agent-write permission, so the red
Cancel run button is not shown to everyone. The section also
depends on what your organisation has: both entries are gated on the AI Agents
module, so without it the AI group does not appear in the left
menu, and starting a run also needs the AI feature on your licence.
What's on this screen
The AI Dashboard has nothing to fill in. The heading
AI Dashboard sits top left with a one-line description; top right
is a purple Open AI Agents button, the only action in the page
body. Below, the AI Agents band shows seven count cards —
Total runs, then Completed, Degraded,
Running, Queued, Failed and
Cancelled. In the captured screen these read 54, 37, 6, 0, 0, 0 and
11; your own figures will differ.
Below that, the AI Usage band shows four cards —
Total calls, Total tokens, Succeeded and
Failed — counting every AI call in the organisation, not only agent
runs. Under those, the By operation panel lists up to eight kinds
of AI task with the calls and tokens each has used. Two rows show a call count
and no token figure: token use is not recorded for every operation, and "0
tokens" would read as a measured zero rather than a missing number.
At the foot is Recent agent runs — the five newest runs with
their type, status and timestamp; only its heading is in view in this capture.
Before any run exists it reads No agent runs yet. The steps below
match the markers on the screenshot.
- Check the account name at the top right. Every AI call is recorded against the signed-in account, and a Viewer is sent to the "not authorised" page rather than seeing these cards.
-
Note the
RISKSgroup in the left menu. The risk register lives there, and a Risk Assessment run can only reason about risks recorded in it. -
Note the
COMPLIANCEgroup below it. Frameworks, controls and their implementation status sit here, and a Compliance Analysis run draws on them. -
Open the
AIgroup further down. It expands to show this dashboard, the AI Agents page — the two entries this chapter covers — and, where the Playbooks module is switched on, Playbooks.
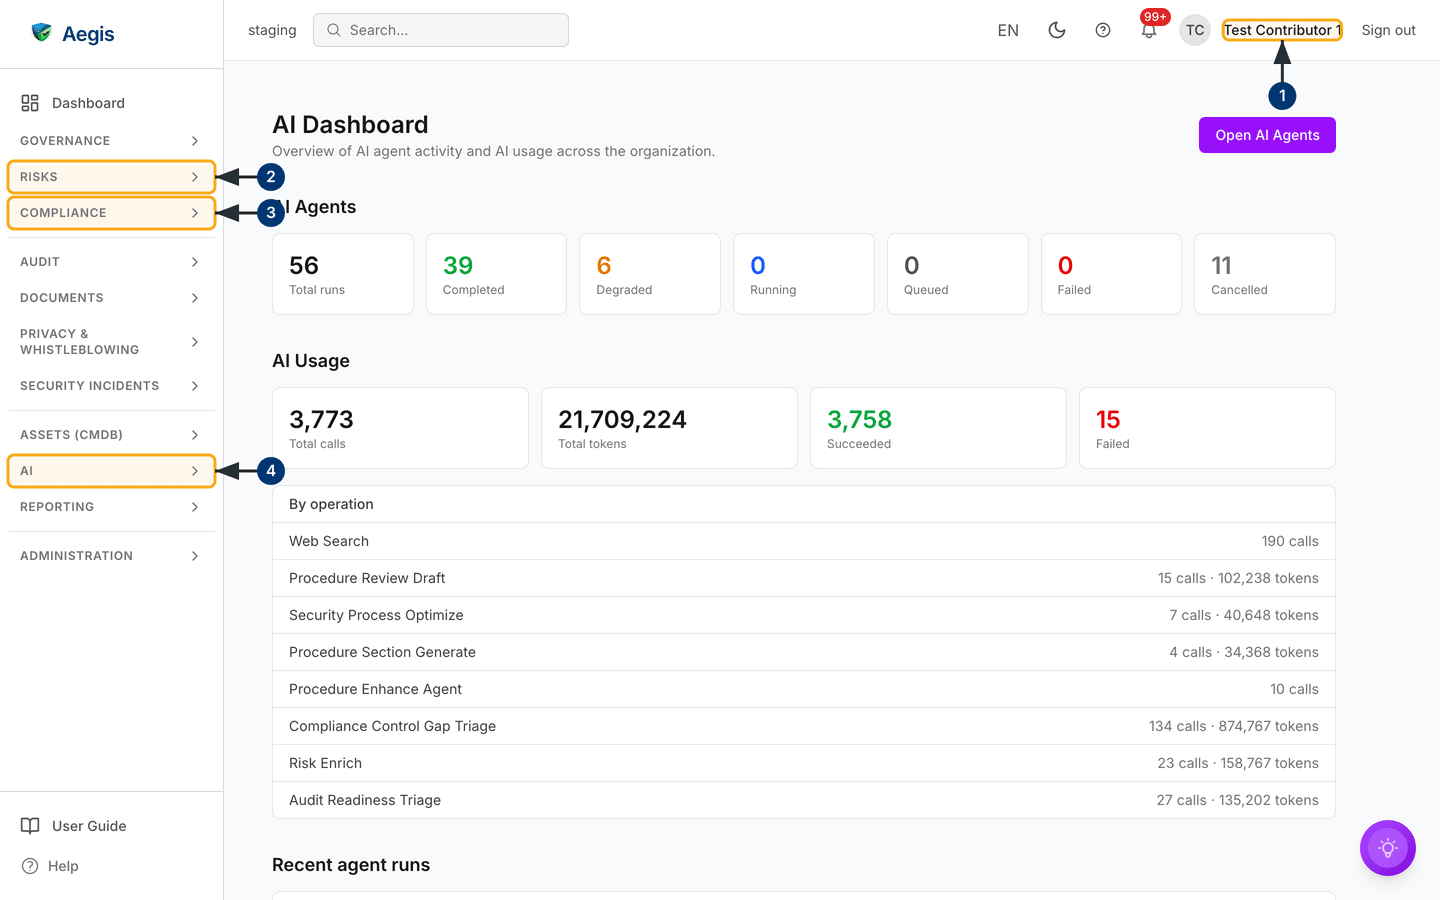
Read the cards as a health check rather than a place to act:
| Card | What it tells you |
|---|---|
Completed |
Finished, with a result you can open and read. |
Degraded |
The agent answered but could not reach your GRC data, so the text is generic framework material, not an analysis of your records. The run detail says so in an orange banner. |
Running |
Reasoning in the background right now. |
Queued |
Submitted but not yet picked up. A count that stays high suggests the background worker is busy or stopped. |
Failed |
Stopped on an error. A rising count is worth checking with your administrator. |
Cancelled |
Stopped by a person before it finished. Only the
Cancel run button sets this — nothing cancels a run
automatically.
|
Opening the agents page
The Open AI Agents button at the top right of the dashboard takes
you to /ai/agents; the AI group in the left menu gets
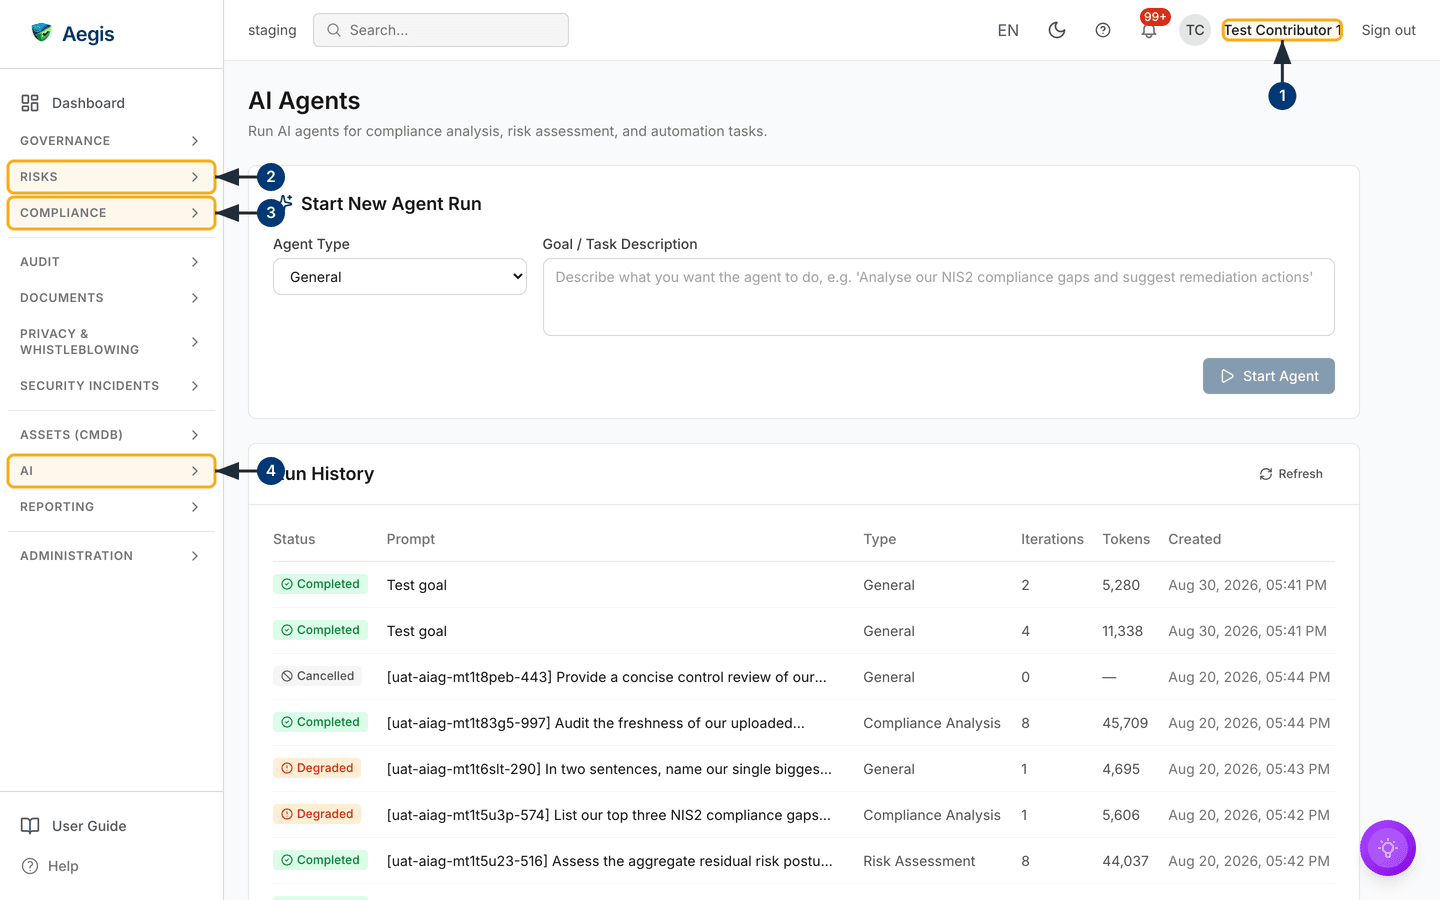
you there too. The page has two panels: Start New Agent Run,
with an Agent Type dropdown, a
Goal / Task Description box and a Start Agent button;
and Run History below it, with a Refresh control
at its right-hand end and a table of every past run — Status,
Prompt, Type, Iterations,
Tokens and Created. In the captured screen the form is
empty, Start Agent is greyed out, and the history shows a mix of
Cancelled, Completed and Degraded runs.
- Confirm the account at the top right before you start anything. The run is logged against it, and the whole organisation can see it in the history.
-
Record the risk you want examined under
RISKSfirst. A Risk Assessment run can only reason about risks already in the register; the sentence you type points it at them, it does not supply them. -
COMPLIANCEsits below it: the frameworks and controls a Compliance Analysis run reasons over. -
The
AIgroup is the way back to the dashboard once a run is going and you want to watch the counts move.
Starting a run
-
Choose an
Agent Type. The dropdown offersCompliance Analysis,Risk AssessmentandGeneral, and opens onGeneral. The type sets the instructions the agent works under — it steers what it reaches for first, framework controls and gaps or the risk register. Every run started from this form goes through the same general handler and the same read-only lookups; the type is not a different engine. -
Write the goal in
Goal / Task Description. Be specific — "check compliance" gives the agent almost nothing, while "list the NIS2 controls we have marked as not implemented and suggest evidence for each" gives it a direction. The grey placeholder shows an example. -
Select
Start Agent. It stays greyed out until the goal box has text in it, then showsStarting…, clears the form back toGeneral, and reloads the history from page one with your run at the top. If the request is refused, a red line appears aboveStart Agentand nothing is submitted.
Watching a run and reading the result
A run works in the background, so nothing spins while you wait. Come back and reload the list.
-
Select
Refreshat the right-hand end of theRun Historyheader. The icon spins and the table reloads in place, without a full page load. -
Read the row.
Iterationscounts the reasoning steps taken, andTokensreads—until there is a figure to show. -
Select any row to open the
Agent Runwindow: status badge, agent type, the fullPromptand, once finished, theResult. A failed run shows anErrorsection instead; a degraded run shows an orange banner warning that the agent could not read your data. -
Read
Tool callsbelow the result, where the agent used any: each step names the lookup it made and shows what came back. It is the quickest way to judge whether an answer rests on your records. -
Act on it. Directly under the result,
Save as recordstores the text as an AI insight linked back to this run, andCreate action itemopens a short form — the description is prefilled from the answer, you write the title — and only appears if your role may create action items.Copysits in the window footer and takes the text to your clipboard. These three appear only once a run has an answer to act on; a run stillQueuedorRunningshows a redCancel runbutton in the footer instead, where your role allows it.
The table shows twenty runs to a page, newest first. When there is more than one
page, a line underneath reads Showing 1–20 of N runs on the left
and Previous / Page 1 of N / Next on the
right. It lists every run in the organisation, not only your own, with no
per-person filter. Before the first run it shows No agent runs yet;
if the list cannot load, it shows Failed to load agent runs with a
Try again button.
The AI assist
The form takes one free-text goal, so what an agent is good for is a matter of what you ask it. Goals that tend to repay the wait:
- Summarising a document — its obligations, who it applies to, and clauses that read ambiguously.
- Suggesting a classification — asking for a category, and a likelihood and impact band, as a starting point for your own judgement. The answer is text; nothing is written to the risk register.
- Drafting a procedure — purpose, scope, steps, roles and references, for you to correct.
- Explaining a requirement — what a control or article asks for.
In every case the agent produces text and stops. Turning that text into something binding is a decision a person makes with a button. The AI assists; the organisation decides.
Tips and limits
- The model can state wrong things with confidence — hallucination. The risk is highest with article numbers, recent legal changes and contract wording. Check against the official source.
-
A
Degradedresult is not a failed one, which makes it the easiest to misread. Nothing in it is evidence about your organisation. - "No gaps found" means the agent found none with the information it had — not that your compliance position is sound.
-
A submitted run cannot be edited. If the type or goal was wrong, cancel it
while it is still
QueuedorRunningand start a fresh one; once it has finished, cancelling is no longer offered. - The dashboard counts are organisation-wide totals, with no date filter and no export.
Before AI-drafted text goes into a policy, an audit response or a regulatory submission, read it line by line and correct it. Treat an agent as a drafting tool, not a compliance authority.
Where this connects
AI agents goes further into run types and results. The output sits next to the records it feeds: Policies and Procedures for drafted text, Risks for a suggested classification, Compliance frameworks for the gaps a Compliance Analysis run reasons over, and Action items for tasks raised from a result. Model configuration lives in Settings; role limits are in What each role can do.